


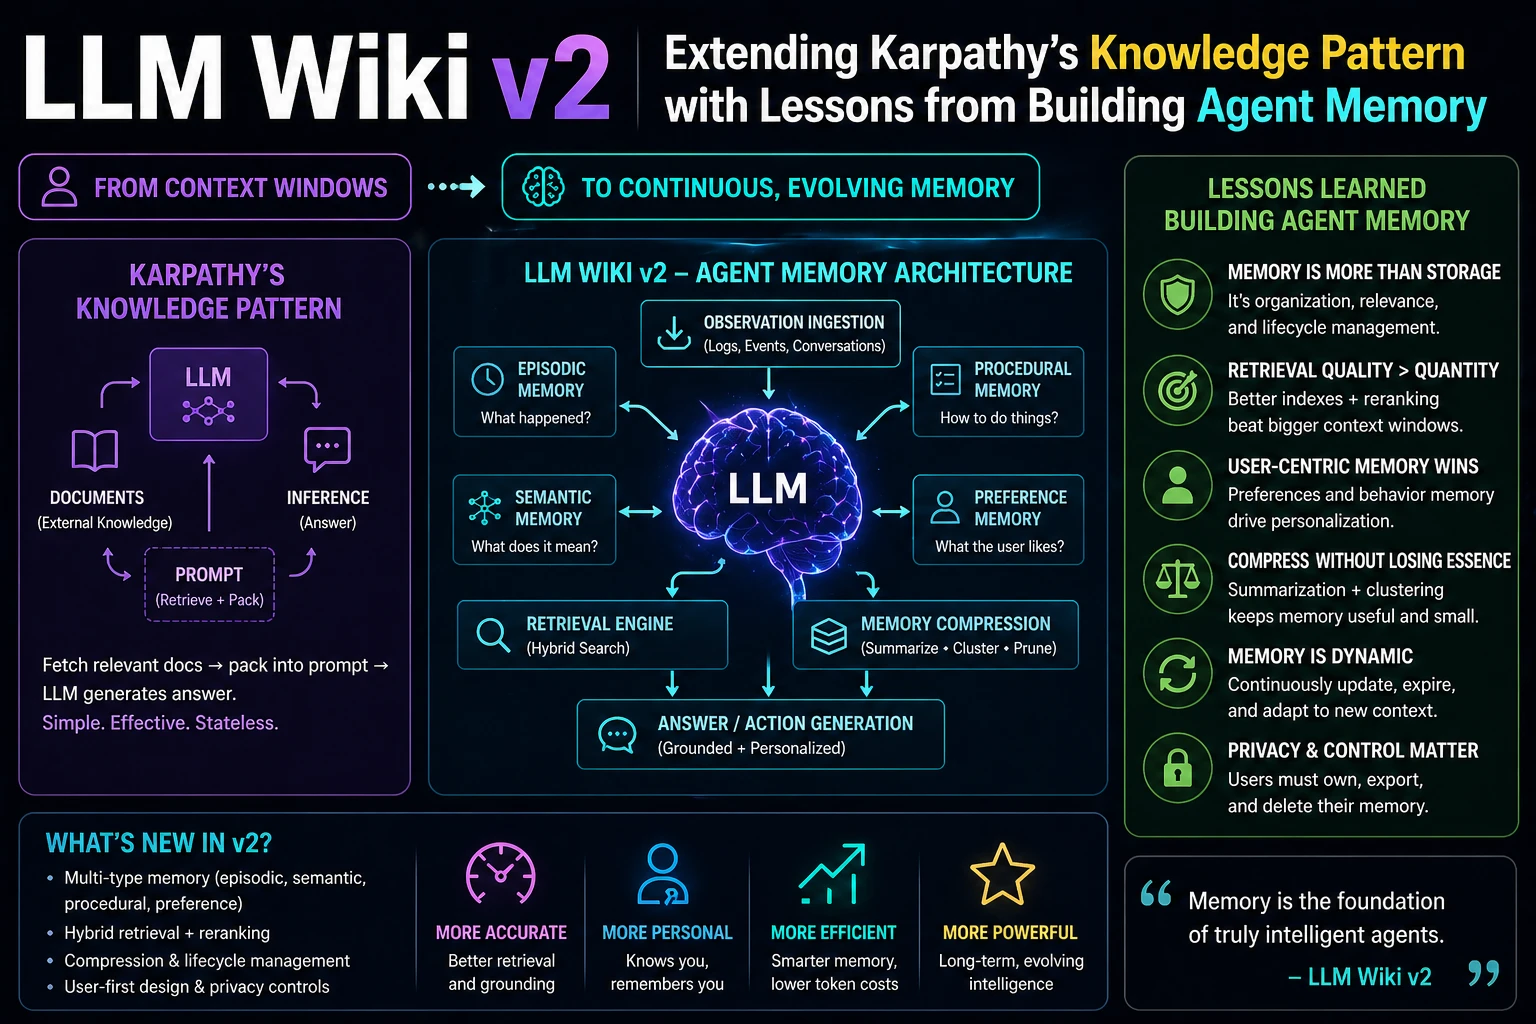
Andrej Karpathy ஏப்ரல் 2026 early-ல "LLM Wiki" Gist publish பண்ணினார் — மூணு வாரத்துல 16 million views cross பண்ணிடிச்சு. Surface-ல வெறும் folder structure-க்கு extraordinary numbers. Pattern simple: structured wiki of context, decisions, entity descriptions maintain பண்ணி — every session start-ல LLM-க்கு feed பண்ணுங்க, real time-ல sprawling knowledge base-ஐ RAG-search பண்றதுக்கு பதிலா.
Pattern resonate ஆன காரணம் — developers quietly struggle பண்ணிக்கிட்டிருந்த problem-ஐ solve பண்ணுது: demos-ல impressive-ஆ பாக்குற RAG systems production-ல rot ஆகுது. 2 வாரம் கழிச்சு, ஏப்ரல் 26-ல developer community LLM Wiki v2 publish பண்ணியிருக்கு — Karpathy pattern-ஐ production agent systems-ல run பண்ண hard-won lessons-ஓட extend ஆகுற Gist. 24 hours-ல 985 stars + 143 forks.
Existing products-ல AI features build பண்ண Indian developers-க்கு — இது இந்த மாசத்துல most practically useful AI engineering content. v2 actually என்ன add பண்ணுது.
Karpathy-ன் Original Pattern என்ன சொன்னது
Original LLM Wiki Gist propose பண்ணது — உங்க codebase context-ஐ LLM-க்கான Wikipedia மாதிரி treat பண்ணுங்க:
.mdfiles-ஓட ஒரு folder, important entity-க்கு ஒரு file (classes, modules, decisions, people, terminology)- Simple
[[double brackets]]-ஐ use பண்ணி cross-linked - Every coding session start-ல LLM-ன் context-க்கு load ஆகுது
- System evolve ஆகும்போது humans (LLM-ம்) update பண்ணுறாங்க
ஏன் take off ஆச்சு: இது RAG-ன் opposite. Retrieval right chunk find பண்ணும்-ன்னு hope பண்றதுக்கு பதிலா, entire relevant context-ஐ up front LLM-க்கு கொடுக்குறீங்க. 1M-token context windows இப்போ standard (DeepSeek V4, GPT-5.5, Qwen 3.6) — finally affordable ஆச்சு.
v2 என்ன Broken-ஆ Identify பண்ணியிருக்கு
v2 authors pattern-ஐ scale-ல run பண்ணினாங்க (அவங்க "agentmemory" project AI coding agents-க்கான persistent memory engine), exactly என்ன fail ஆகுது-ன்னு document பண்ணியிருக்காங்க:
1. Wikis Rot ஆகுது — Fast
Lifecycle management இல்லாம, wiki current code-ஐ contradict பண்ண stale entries accumulate ஆகும். LLM, agreeable-ஆ இருக்கறதால, wiki-ஐ follow பண்ணும். Bugs ensue ஆகும். v2 prescribe பண்ணுது — entry per explicit "freshness" metadata: எப்போ last verified, யாரால, code-ன் எந்த version-க்கு against.
2. Cross-Links Junk-ஆ ஆகும்
Karpathy-ன் [[double brackets]] 50 entries-க்கு work ஆகும். 500-ல unmaintainable orphan-link sprawl-ஆ ஆகும். v2 introduce பண்ணுது — typed relationships — "depends-on", "supersedes", "owned-by", "implements" — semantic web + ontology engineering-ல இருந்து borrowed. LLM அப்போ keyword match மட்டும் இல்லாம graph traversal-ஐ பத்தி reason பண்ண முடியும்.
3. Humans Update பண்ண நிறுத்துறாங்க
Wikis die ஆகுறதுக்கு single biggest reason: யாரும் maintain பண்ண விரும்புறதில்ல. v2 propose பண்ணுது — automation hooks — git pre-commit hooks dev-ஐ prompt பண்ணும் "இந்த class change பண்ணினீங்க, அதோட wiki entry update பண்ணுங்களா?", LLM-generated drafts human approve பண்ணினா போதும்.
4. Quality Silently Erode ஆகும்
v2 add பண்ணுது — quality controls — periodic audit prompts: wiki-ல contradictions find பண்ண LLM-ஐ ask பண்ணுது, plus entry per "trust score" — verification இல்லாம time-ல decay ஆகுது.
Practical Architecture
v2 file structure-ஐ concrete terms-ல spell out பண்ணுது:
llm-wiki/
├── _meta/
│   ├── conventions.md       # wiki எப்படி organise ஆகியிருக்கு
│   ├── ontology.md          # typed relationships
│   └── audit-log.md         # எப்போ என்ன check ஆச்சு
├── entities/
│   ├── classes/
│   ├── modules/
│   ├── people/
│   └── decisions/
├── relationships.json       # graph layer
└── README.md                # first load ஆகுற entry point
relationships.json file v2-specific innovation. Typed edges-ஓட flat JSON array. LLM load ஆகும்போது markdown content-ஓட structured graph-ம் கிடைக்கும் — text-pattern matching இல்லாம "என்ன என்ன-ல depend ஆகுது" reason பண்ண விடும்.
Indian AI Developers-க்கு ஏன் Matter பண்ணுது
India-ன் AI developer scene 18 months-ல மூணு phases-ஐ cross பண்ணியிருக்கு:
- Phase 1 (mid-2025): எல்லாத்துக்கும் RAG bolt பண்ணினாங்க
- Phase 2 (early 2026): Scale grow ஆகும்போது RAG visibly underperform ஆக start ஆச்சு
- Phase 3 (now): Long-context LLMs + structured wikis production-grade alternative-ஆ emerge ஆகுது
Legal-tech, fin-tech, healthtech-ல AI copilots ship பண்ண Bengaluru/Hyderabad SaaS teams-க்கு — LLM Wiki pattern "demo works on small dataset" vs "agent actually understands our system in production"-க்கு இடையே missing piece. v2-ன் lifecycle + quality patterns deployable-ஆ ஆக்குது.
Existing Project-ல v2 எப்படி Adopt பண்ண
Laravel/Django/FastAPI codebase run பண்ணுறீங்க, இதை try பண்ண நினைக்கறீங்க-ன்னா:
- 5 entries-ஓட start பண்ணுங்க — top 5 domain entities (User, Order, Payment, etc.). Day 1-ல entire codebase-ஐ wiki பண்ண try பண்ணாதீங்க.
- v1-ஐ LLM-ஐ வச்சு auto-generate பண்ணுங்க — Claude அல்லது DeepSeek-ஐ வச்சு code walk பண்ணி initial drafts produce பண்ணுங்க. Each one human-review.
- relationships.json add பண்ணுங்க — 5 entries-க்கு இடையே explicit dependencies list பண்ணுங்க. v2-suggested types (depends-on, implements, supersedes) use பண்ணுங்க.
- Git pre-commit hook wire பண்ணுங்க — v2 Gist sample bash hook include பண்ணியிருக்கு — changed files-ஐ wiki-ஐ against diff பண்ணி updates-க்கு prompt பண்ணும்.
- Freshness audit cadence set பண்ணுங்க — weekly job, git activity vs wiki last-updated-at-ஐ வச்சு stale entries flag பண்ண LLM-ஐ ask பண்ணும்.
- Iterate — LLM session noticeably benefit ஆனா மட்டும் புது entities add பண்ணுங்க.
Total setup time: small codebase-க்கு half a day. Cost discipline-ல, tooling-ல இல்ல.
v2 இன்னும் Solve பண்ணாதது
v2 authors acknowledge பண்ண honest limitations:
- Multi-language wikis — currently English-only assumption. Indian polyglot codebases (English code-ல Tamil/Hindi domain terms) — translation layer தேவை, இன்னும் specify ஆகல.
- Non-code knowledge-க்கு wiki — code-க்கு well work ஆகுது; organisational knowledge-க்கு (HR policies, customer history) எப்படி adapt பண்றது-ன்னு less clear.
- Multi-agent contention — 3 agents simultaneously wiki-ஐ update பண்ண try பண்ணினா locking அல்லது conflict resolution தேவை. v2 hand-wave பண்ணுது.
- Scale-ல cost — every LLM call-ல 50KB wiki context load பண்றது add up ஆகும். 10M-call/month workload-க்கு pricing analysis useful, v2-ல இல்ல.
Deeper Argument
v2-ன் core thesis unfashionable, ஆனா probably correct: RAG என்பது 2023-ல 8K-context LLMs-க்கான workaround. 1M-token windows இப்போ standard, price drop ஆகுது (DeepSeek V4-Pro per 1M output tokens ₹185) — retrieval-ஐ விட inclusion-க்கான economic case every quarter weaken ஆகுது.
Last year vector DB pipeline build பண்ணி இப்போ maintenance load-ல creak ஆகுது-ன்னா — Indian AI engineer-ஆ நீங்க v2 படிங்க. Religious conversion-ஆ இல்ல, அடுத்த project-க்கு consider பண்ண pragmatic alternative-ஆ.
எங்க கிடைக்கும்
GitHub Gist-ல "LLM Wiki v2" search பண்ணுங்க, அல்லது original Karpathy Gist-ல linked v2 check பண்ணுங்க. Community Hacker News + Latent Space Discord-ல actively discuss பண்ணுது. Indian AI engineering communities (BangaloreAI, MadrasML) pattern-ஐ pathi study groups start பண்ணியிருக்காங்க.





கருத்துகள் (0)
Be the first to comment!