


Key Takeaways
- Bodhan AI, AI4Bharat உடன் இணைந்து செப்டம்பர் 2, 2026 அன்று OCR, Translation, Speech-க்கான நான்கு Indic AI மாடல்களை வெளியிட்டது.
- இந்தி பாடத்தில் English loan words, scanned tables, handwritten equations கலந்த real classroom content-ஐ இந்த மாடல்கள் நேரடியாக target செய்கின்றன.
- AI4Bharat என்பது IIT Madras-linked team; Indic NLP-ல பல வருஷமா வேலை செய்து வரும் குழு இது.
- Digital education platforms, state board digitisation, non-English first users-க்கு searchable archive மற்றும் regional translation-ல நேரடி boost கிடைக்கும்.
- Clean English text மட்டும் அல்லாமல் Indic scripts மற்றும் code-mixed sentences-க்கு வேலை செய்யும் AI-க்கு இந்தியாவின் push-ஐ இந்த release பிரதிபலிக்கிறது.
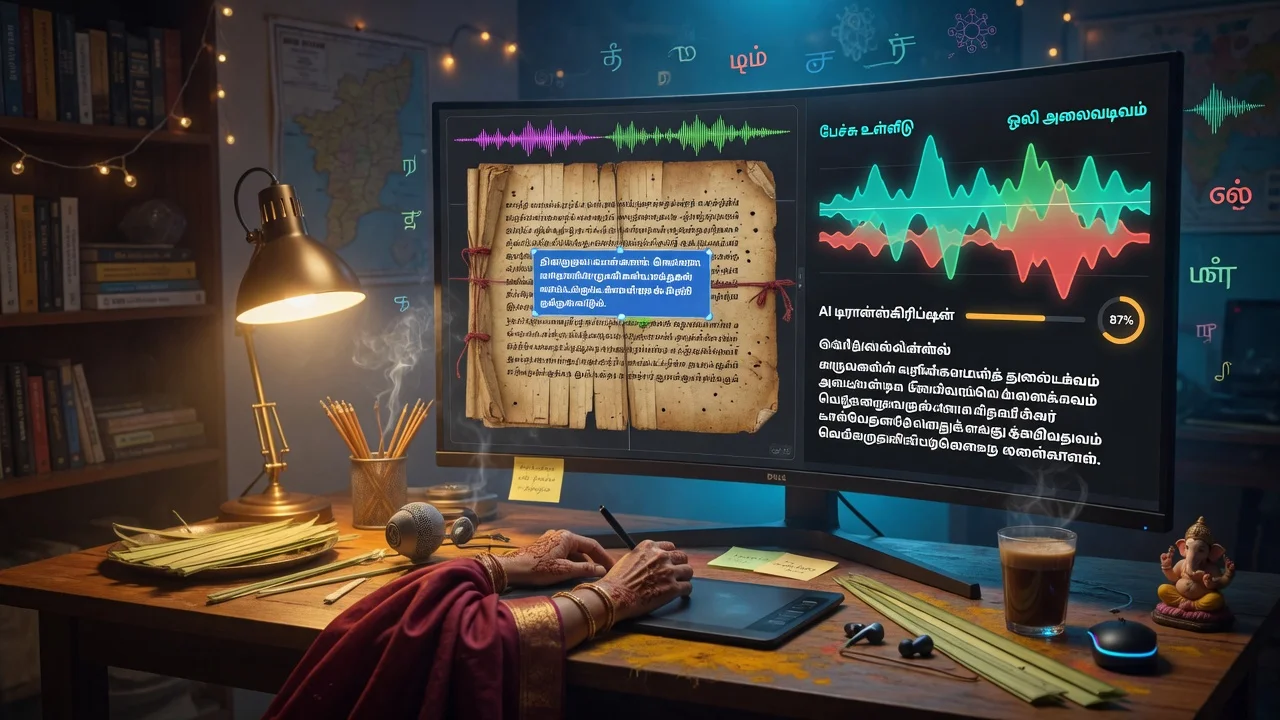
ஒரு Hindi science பாடம் எடுத்துக்கோங்க. ஆசிரியர் blackboard-ல force, velocity போன்ற English terms எழுதுவார். Textbook scanned PDF-ஆ இருக்கும். உள்ளே tables இருக்கும். மாணவர்கள் equations-ஐ கையால் எழுதிய notes போட்டிருப்பாங்க. இந்த pile-ஐ search பண்ணணும், Tamil அல்லது Kannada-க்கு translate பண்ணணும், audio-வா கேட்கணும்னா ஒரு mega chatbot போதாது. Specialised models வேணும்.
அந்த gap-ஐ close பண்ண Bodhan AI, AI4Bharat உடன் சேர்ந்து செப்டம்பர் 2, 2026 அன்று நான்கு Indic AI மாடல்களை வெளியிட்டுள்ளது. OCR, Translation, Speech — இந்த மூன்று core pain points-ஐ இந்திய மொழிகளில் நேரடியாக handle செய்யும் நோக்கம் இது. Ordinary LLM announcement இல்ல. Practical classroom மற்றும் office வேலைக்கான tool set.
என்ன நடந்தது?
Bodhan AI நான்கு புதிய Indic models-ஐ public-ஆ வெளியிட்டுள்ளது. இவை OCR, Translation, Speech tasks-ஐ இந்திய மொழிகளில் கையாளும். Release தேதி செப்டம்பர் 2, 2026. இது AI4Bharat உடன் இணைந்த வேலை. AI4Bharat என்பது IIT Madras-linked team. Indic natural language processing-ல பல வருஷமா datasets, benchmarks, models உருவாக்கி வருகிறது. English-first tools-ல Devanagari, Tamil script, code-mixed sentences choke ஆகும் பிரச்சினையை இந்த ecosystem நேரடியாக address செய்கிறது.
Indian edtech platforms, government digitisation drives, regional content creators இதுவரை பொதுவான OCR மற்றும் translation tools-ஐயே use பண்ணிட்டு இருந்தாங்க. அந்த tools clean English document-க்கு okay. ஆனா Hindi headings + English formulas கலந்த Class 10 science PDF வந்தா garbage text தான் கிடைக்கும். இந்த நான்கு models அந்த mess-ஐ target செய்கின்றன.
ஏன் இது classroom mess-க்கு முக்கியம்?
இந்தியாவில real educational content pure language-ல இருக்காது. Teachers English technical terms போடுவாங்க. Loan words வரும். Sanskrit-derived words கலக்கும். Textbooks பெரும்பாலும் scans. Old government circulars-ம் scanned PDFs தான். Tables வந்தா ordinary OCR engines உடையும். Handwritten maths, science notes இன்னும் கஷ்டம்.
இந்த pile searchable-ஆ இல்லனா digital archive என்பது dead PDF folder தான். Translate பண்ணனும்னா meaning break ஆகும். Aloud படிக்கணும்னா pronunciation மற்றும் code-mix fail ஆகும். Bodhan AI + AI4Bharat models இந்த மூன்று சுவர்களையும் ஒரே pipeline-ல பார்க்க முயற்சிக்கிறது. Educational content-ஐ searchable-ஆ மாத்துவது, இந்திய மொழிகளுக்கு translate செய்வது, aloud படிக்கக்கூடியதாக மாற்றுவது — இந்த மூன்றும் digital education-க்கு அடிப்படை.
State board digitisation drives-ல ஆயிரக்கணக்கான பழைய books, notes, circulars scan ஆகிக்கிட்டு இருக்கும். அவை text layer இல்லாம இருந்தா search வேலை செய்யாது. Non-English first users — Tamil, Kannada, Marathi, Bengali medium students — English-only tools-ல சிக்கிடுவாங்க. இந்த models அந்த users-க்கு நேரடி boost கொடுக்கும் என்று எதிர்பார்க்கலாம்.
OCR: முதல் சுவர்
Indian textbooks, பழைய government circulars எல்லாம் scans-ஆ இருக்கும். Tables வந்தா பெரும்பாலான OCR engines உடையும். Handwritten maths, science notes இன்னும் கடினம். Devanagari, Tamil, Telugu மற்றும் உள்ளே கலந்திருக்கும் English bits-ஐயும் handle பண்ணும் Indic-focused OCR model இருந்தா searchable archive கிடைக்கும். இல்லனா folder-ல PDF குவிந்துகிட்டே இருக்கும்.
உதாரணத்துக்கு ஒரு Class 10 science PDF எடுங்க. Table-ல Hindi headings இருக்கும். உள்ளே English formulas. Normal OCR அதை broken characters மற்றும் wrong layout-ஆ மாத்திடும். Indic-focused model proper text layer கொண்டு வர முயற்சிக்கும். அப்போதான் student அல்லது teacher keyword search பண்ண முடியும். Library digitisation, school archive, coaching notes — எல்லாத்துக்கும் இது அடிப்படை requirement.
Handwritten equations தனியா ஒரு challenge. Students notebook-ல எழுதிய maths steps-ஐ machine-ஆ படிக்கணும்னா general OCR போதாது. Indic scripts + maths symbols + mixed English labels — இந்த combination-க்கு dedicated training வேணும். இந்த release அந்த திசையில ஒரு practical step.
Translation: code-mix-ஐ காப்பாத்தணும்
Pure Hindi to pure English ஒரு பிரச்சினை. Real Indian text அதையும் விட கஷ்டம். Sentence Hindi-ல start ஆகும், English technical term drop ஆகும், Sanskrit-derived word-ல முடியும். Commercial translators இதை இன்னும் butcher பண்ணுது. Meaning fly ஆகிடும். Loan words-ஐ அப்படியே விடணுமா, local equivalent போடணுமான்னு confusion வரும்.
Indic data மற்றும் loan-word patterns-ல train ஆன models meaning-ஐ intact வைக்க அதிக வாய்ப்பு. Class 10 science chapter Hindi-ல இருந்து Marathi அல்லது Bengali-க்கு போகும்போது இது தெரியும். "force என்றால் விசை" மாதிரி கலவை வாக்கியங்களை சரியாக கொண்டு போகணும். Technical term-ஐ தவறாக மொழிபெயர்த்தா மாணவருக்கு concept-ே தவறா போயிடும்.
State board content ஒரு மொழியில இருந்து இன்னொரு மொழிக்கு move ஆகும்போது quality முக்கியம். Edtech apps multi-language support கொடுக்கணும்னா code-mixed classroom language-ஐ respect பண்ணும் translation வேணும். இந்த models அந்த gap-ஐ நிரப்ப முயற்சிக்கின்றன. Clean literary text மட்டும் அல்ல; real school மற்றும் office language.
Speech: aloud படிக்கறது simple இல்ல
Text searchable-ஆ ஆனா, translate ஆனா மட்டும் போதாது. பல students மற்றும் parents audio-வா கேட்க விரும்புவாங்க. Commute-ல, வீட்ல multitask பண்ணும்போது, reading difficulty இருக்கும்போது speech output உதவி. ஆனா Indic speech models-க்கு challenge அதிகம்.
Code-mixed sentences-ல Hindi + English terms கலந்து வரும். Proper names, formulas, abbreviations pronunciation-ல fail ஆகும். Regional accents மற்றும் script-specific sounds வேறு. Educational content-ஐ aloud படிக்கும்போது technical terms தவறாக ஒலிச்சா comprehension பாதிக்கும். Speech-focused Indic models இந்த use case-ஐ நேரடியாக பார்க்கின்றன.
Classroom revision, audiobook-style lessons, accessibility for visually challenged learners — எல்லாத்துக்கும் reliable Indic TTS மற்றும் related speech pipelines தேவை. நான்கு models மூன்று pain points-ஐ cover பண்றதுனால OCR → translate → speak என்ற flow practical-ஆ முடியும்.
யாருக்கு நேரடி பயன்?
Digital education platforms முதல் பயனாளிகள். அவங்க library-ல இருக்கும் scanned state board books-ஐ searchable-ஆ மாத்தலாம். Multi-language course content quality மேம்படும். Coaching institutes தங்க notes-ஐ archive பண்ணி keyword search கொடுக்கலாம்.
Government மற்றும் state board digitisation teams-க்கும் இது relevant. பழைய circulars, textbooks, exam materials-ஐ text layer உடன் வைக்கணும்னா Indic OCR முக்கியம். Regional language portals non-English first citizens-க்கு சேவை கொடுக்கும்போது translation மற்றும் speech உதவும்.
Regional content creators — YouTube educators, blog writers, app developers — Devanagari, Tamil, Telugu content-ஐ English-first tools-ல சிக்க வைக்காமல் process பண்ண முடியும். UPI payment screens, Jio ecosystem apps, Flipkart-style vernacular commerce copy எல்லாம் code-mix தான். அதே pattern education content-லயும் இருக்கு. அதனால இந்த models-ன் India angle தெளிவு.
இது ஏன் ordinary chatbot announcement இல்ல?
பொதுவான LLM demo ஒரு box-ல English prompt போட்டு answer வாங்குவது. Classroom mess அதற்கு அப்பறம் இருக்கும். Scanned table layout, handwritten equation, Hindi-English loan word mix, aloud reading with correct technical terms — இதெல்லாம் separate specialised capability. Bodhan AI மற்றும் AI4Bharat இந்த practical stack-ஐ Indic languages-க்கு கொண்டு வர முயற்சிக்கிறாங்க.
India-வின் AI push இப்போ clean English benchmarks மட்டும் பார்க்கல. Indic scripts, code-mixed sentences, real documents — இதெல்லாம் முன்னுரிமை. IIT Madras-linked AI4Bharat நீண்ட நாளா இந்த திசையில datasets மற்றும் models கொடுத்து வருகிறது. இந்த September 2, 2026 release அந்த தொடர்ச்சியின் ஒரு பகுதி.
Tools ready ஆனாலும் adoption தான் next step. Schools, edtech teams, digitisation projects இந்த models-ஐ pipeline-ல போட்டு accuracy test பண்ணணும். Tables, handwriting, heavy code-mix — எங்க fail ஆகுதுனு பார்த்து feedback கொடுக்கணும். அப்போதான் searchable, translatable, speakable Indic educational archive உண்மையிலேயே நகரும்.
சுருங்கச் சொன்னா: Hindi lesson-ல English terms, scanned tables, handwritten equations — இந்த mess தான் இந்திய digital education-ன் daily reality. Bodhan AI-யின் நான்கு Indic models அந்த reality-யை OCR, Translation, Speech மூலம் handle பண்ண ஒரு practical முயற்சி. Clean PDF folder-ஐ living, searchable, multi-language knowledge base-ஆ மாற்றற திசையில இது ஒரு தெளிவான அடி.



கருத்துகள் (0)
Be the first to comment!