


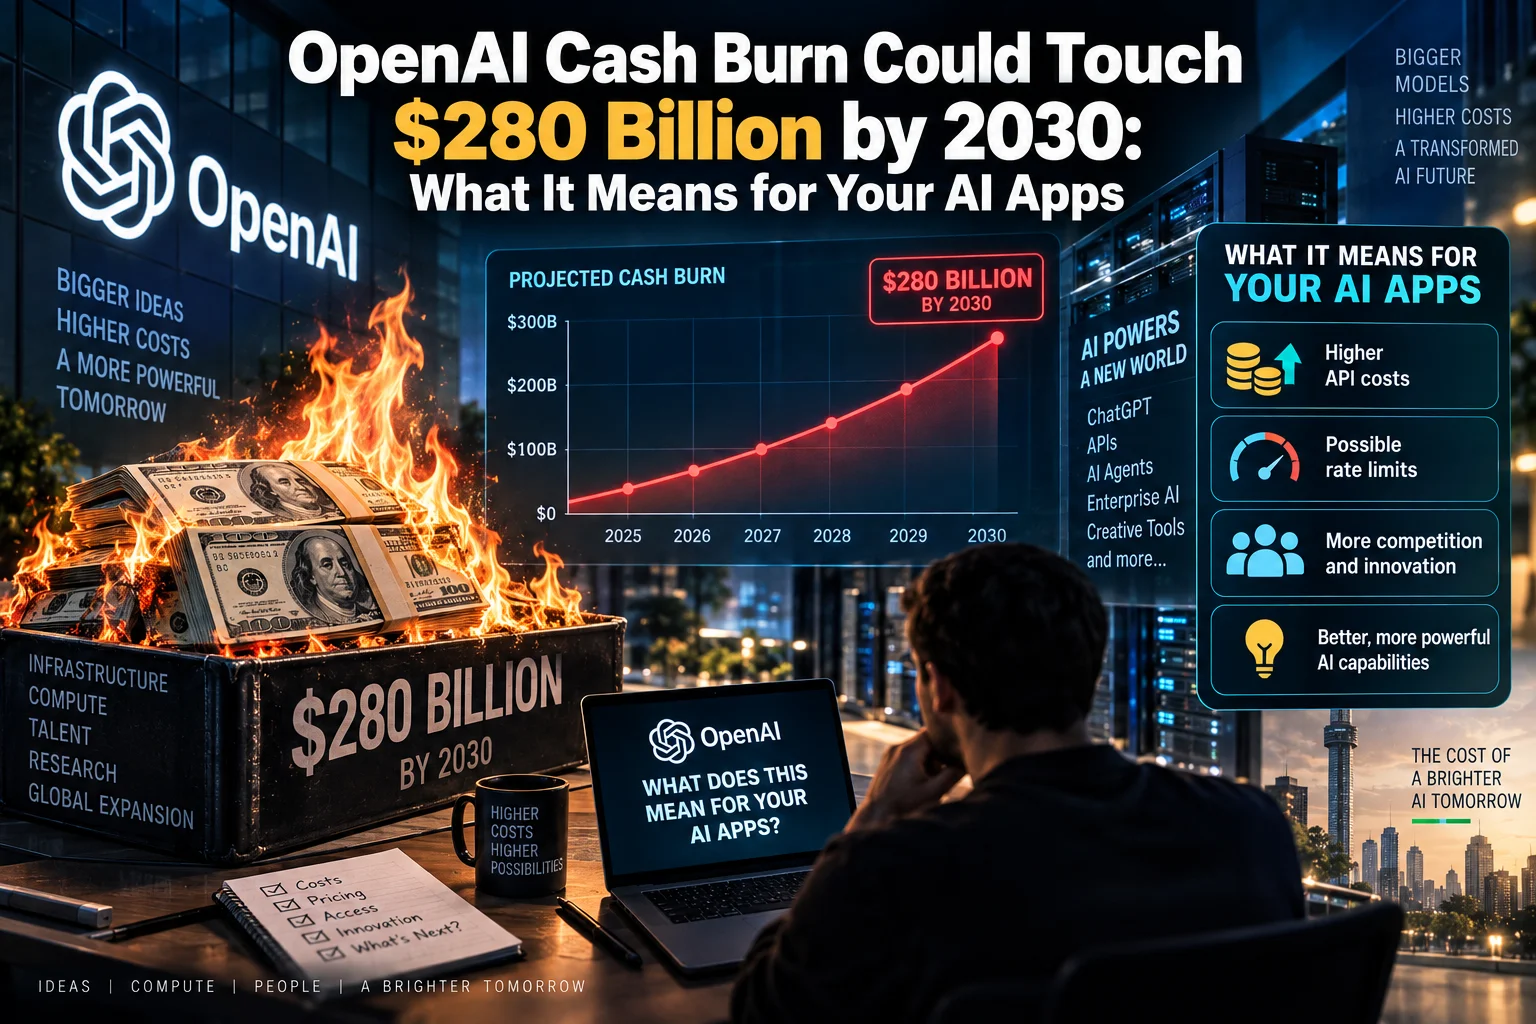
தமிழ்நாட்டு அன்றாட உதாரணங்கள்: நம்ம வாழ்க்கையில என்ன மாறும்?
சென்னை IT Corridor-ல வேலை பார்க்கும் ஒரு Junior Developer-ஐ யோசிங்க. தினமும் Code debug பண்ண, meeting notes summarize பண்ண, client mail draft பண்ண ChatGPT Free-யை open பண்ணுவார். இப்போவரை limit தெரியாம பயன்படுத்தினாலும், cash burn இவ்வளவு பெரிசா இருக்கும்போது free tier-ல rate limit விரைவில் இறுக்கமாகும். அப்போ ஒரே நாள்ல இரண்டு மூணு முக்கிய task முடியாம நிக்கும். Coimbatore-ல small textile business ஓட்டும் owner invoice summary, WhatsApp customer reply template எல்லாம் AI-ல செஞ்சு வந்திருப்பார்; subscription கட்டணம் உயர்ந்தா அந்த monthly expense-ஐ மறுபரிசீலனை செய்ய வேண்டியிருக்கும். Madurai college student project report, assignment outline-க்கு free credits-ஐ நம்பி இருந்தா, mid-semester-ல access குறைஞ்சா alternate tool இல்லாம சிக்கல் வரும். இது hypothetical பயம் இல்ல; compute bill உயரும்போது consumer side-ல first hit free users-க்குதான் வரும்.
Chennai-ல freelance content writer-களும் Trichy-ல tuition centre tutors-உம் long PDF summarize, question paper generate பண்ண daily AI use பண்றாங்க. Inference cost ஒவ்வொரு response-க்கும் server-ல பில் ஆகும்போது, platform tiered plan கொண்டு வரலாம்—basic chat மட்டும் free, deep research அல்லது long document analysis paid-க்கு மட்டும். Enterprise client-களுக்கு aggressive monetization வரும்போது, small Indian agency-க்கள் API bill shock அடிக்கடி பார்க்கும். அதனாலதான் already பல TN-based product teams frontier API-யை critical path-ல மட்டும் வச்சு, remaining workload-ஐ self-hosted open-weight models-ல shift பண்ற hedge strategy பயன்படுத்துறாங்க. Token bill control பண்ண இது practical step; முழுசா ஒரே vendor-ஐ depend பண்றது risk அதிகம்.
நம்ம phone-ல app notification-ல “usage limit reached” அடிக்கடி வர ஆரம்பிச்சா, அது random glitch இல்ல—backend-ல power contract, GPU cluster, data centre electricity bill-ஓட நேரடி reflection. Software முன்னாடி asset-light-ஆ இருந்தது; இப்போ AI run பண்றது telecom network அல்லது heavy infrastructure போல continuous cost. So Chennai startup founder-ஆ இருந்தாலும், Salem-ல solo creator-ஆ இருந்தாலும், monthly AI budget-ஐ spreadsheet-ல track பண்ண ஆரம்பிக்கணும். Free forever expect பண்ற mindset-ஐ விட்டு, paid tier value மற்றும் open-source fallback இரண்டையும் parallel-ஆ prepare பண்றதுதான் daily-life-ல real preparation.
பொதுவான தவறுகள், Step-by-step தயாரிப்பு, அடுத்தது என்ன எதிர்பார்க்கலாம்
முதல் common mistake: ஒரே tool-ஐ மட்டும் “எல்லாம் இதுலயே முடியும்”னு bind பண்றது. ChatGPT slow ஆனா அல்லது limit முடிஞ்சா வேலை நின்னுடும்னு நினைக்கிறவங்க Gemini, Claude, open-weight local options-ஐ முன்னாடியே try பண்ணாம இருக்காங்க. இரண்டாவது தவறு: API key-ஐ production app-ல unlimited call போட்டு bill பார்க்காம விடுறது—token meter பாக்காம pilot success-ஐ scale பண்ணிட்டு monthly invoice பார்த்து shock ஆகிற Indian teams நிறைய. மூணாவது: free student credits-ஐ permanent plan-ஆ நினைச்சுக்கிறது; credits expire ஆனதும் alternate workflow இல்லாம project delay. நான்காவது: self-host பண்ணனும்னு சொல்லி GPU cost, power, maintenance estimate பண்ணாம laptop-லயே “full company model” ஓட்ட முயற்சி—performance fail ஆகும். இந்த தவறுகளை தவிர்க்க comparison mindset வேணும்: frontier model quality vs open-weight cost control vs hybrid routing.
Step-by-step-ஆ இப்போ என்ன பண்ணலாம். ஒன்று: நீங்க daily use பண்ற AI tasks-ஐ list போடுங்க—mail draft, code help, PDF summary, image ideas என category பிரிங்க. இரண்டு: ஒவ்வொரு category-க்கும் primary tool மற்றும் backup tool fix பண்ணுங்க; ஒரு week test use பண்ணி quality note எழுதுங்க. மூன்று: paid subscription இருந்தா usage dashboard பார்த்து எந்த feature real-ஆ worth-னு measure பண்ணுங்க; fancy feature-க்கு பணம் போடாதீங்க. நான்கு: developer அல்லது startup team என்றால் critical prompts-ஐ frontier API-லயும், bulk repetitive calls-ஐ self-hosted open-weight model-லயும் split பண்ண architecture design பண்ணுங்க. ஐந்து: electricity மற்றும் server cost Indian office-ல self-host-க்கு realistic-ஆ இருக்கா என்று small pilot மட்டும் ஓட்டி பாருங்க; full migration உடனே வேண்டாம். ஆறு: policy change notification-ஐ ignore பண்ணாதீங்க—terms, rate limit, pricing mail வந்தா team-க்கு share பண்ணுங்க. இந்த sequential habit cash burn news-ஐ personal action-ஆ மாற்றும்.
அடுத்ததாக என்ன expect பண்ணலாம் என்றால், free tier மேலும் tight-ஆவதும், subscription tiers அதிகரிப்பதும், enterprise sales pressure அதிகரிப்பதும் natural direction—ஏனென்றால் training மற்றும் inference scale-க்கு GPU clusters, custom silicon, data centre power contracts தேவை, அது $280 billion அளவு cumulative burn-ஓட connect. Valuation talks $1.2 trillion திசையில் போனாலும், public listing முன் investors return expect பண்ணுவாங்க; அதனால் monetization lock soft-ஆ இருக்காது. Indian tech founders-க்கு இது panic signal இல்ல, planning signal. Comparison-ல பார்த்தா old software download model போல infinite free scale இனி frontier AI-ல expect பண்ண முடியாது; telecom recharge mindset-க்கு நெருக்கமா user experience மாறலாம். So quality-க்கு frontier API, cost control-க்கு open-weight, flexibility-க்கு multi-tool habit—இந்த மூணு அடுக்கு தமிழ்நாட்டு readers-க்கு next few years practical shield. Facts மாறாது: compute billதான் driver; user side-ல preparationதான் control-ல இருக்கும் ஒரே விஷயம்.
பழைய Software Model vs Frontier AI: Comparison மற்றும் TN Teams என்ன expect பண்ணலாம்
முன்னாடி software business asset-light-ஆ இருந்தது—code எழுதி server-ல upload பண்ணினா millions of users download பண்ணலாம், extra cost பெரிசா ஏறாது. Frontier AI அந்த rulebook-ஐ முழுசா மாத்திருக்கு. Training phase-ல thousands of high-end Nvidia chips மற்றும் custom accelerators months together uninterrupted ஓடணும்; data centre-ல gigawatt-scale power, liquid-cooling, multi-billion-dollar network fabric வேணும். Inference phase-ல நீங்க ChatGPT-ல code debug, PDF summary, mail draft கேட்கும் ஒவ்வொரு response-க்கும் real-time-ல billions of calculations நடக்கும். So old download-and-forget model இல்ல; இது telecom network அல்லது heavy infrastructure ஓட்டுற continuous burn pattern. OpenAI cumulative cash burn 2030 வரை roughly $280 billion—அதாவது ₹23-24 lakh crore அளவு—GPU clusters, custom silicon, power contracts, electricity-ஓட connect. Valuation talks $1.2 trillion திசையில் போனாலும் investors return expect பண்ணுவாங்க; அதனால் free forever mindset practical இல்ல.
Comparison-ல பார்த்தா Chennai product team-க்கு clear picture கிடைக்கும். Critical reasoning, complex client demo, high-stakes code review—இதுல frontier API quality தேவை. ஆனா bulk repetitive tasks, internal FAQ draft, simple template generation—இதுல self-hosted open-weight model போதும், token bill control ஆகும். Already பல Indian development teams இந்த hybrid hedge use பண்றாங்க: frontier API-ஐ critical path-ல மட்டும் வச்சு, remaining workload-ஐ open-weight-க்கு shift. Common expectation mistake என்னன்னா, subscription ஒருத்தர் கட்டினா office முழுக்க unlimited-னு நினைக்கிறது; tiered plans மற்றும் rate limit வரும்போது shared account-ல conflict வரும். இன்னொரு miss: enterprise monetization pressure consumer free tier-ஐயும் இறுக்கும்—so solo freelancer-ஆ இருந்தாலும் small agency-ஆ இருந்தாலும் usage dashboard weekly பார்க்கணும்.
Next few years-ல என்ன expect பண்ணலாம் என்றால் tighter free limits, more subscription tiers, aggressive enterprise sales natural direction. Training cost மற்றும் inference scale இரண்டும் குறையாம இருக்குன்னா platform side monetization soft-ஆ இருக்காது. Tamil Nadu readers-க்கு practical shield மூணு அடுக்கு: quality வேணும்போது frontier API, cost control-க்கு open-weight local or self-hosted option, flexibility-க்கு multi-tool habit—Gemini, Claude, open models backup-ஆ ready வைக்கணும். Full migration உடனே வேண்டாம்; small pilot-ல electricity, maintenance, latency measure பண்ணிட்டுதான் expand பண்ணுங்க. Facts மாறாது—compute billதான் driver; user side-ல preparation, hybrid routing, budget trackingதான் நம்ம control-ல இருக்கும் ஒரே விஷயம். Panic வேண்டாம்; spreadsheet-ல AI spend track பண்ணி, backup workflow fix பண்ணி, policy mail ignore பண்ணாம team-க்கு share பண்ணுங்க—இதுவே daily-life-ல real readiness.



கருத்துகள் (0)
Be the first to comment!