


Key Takeaways
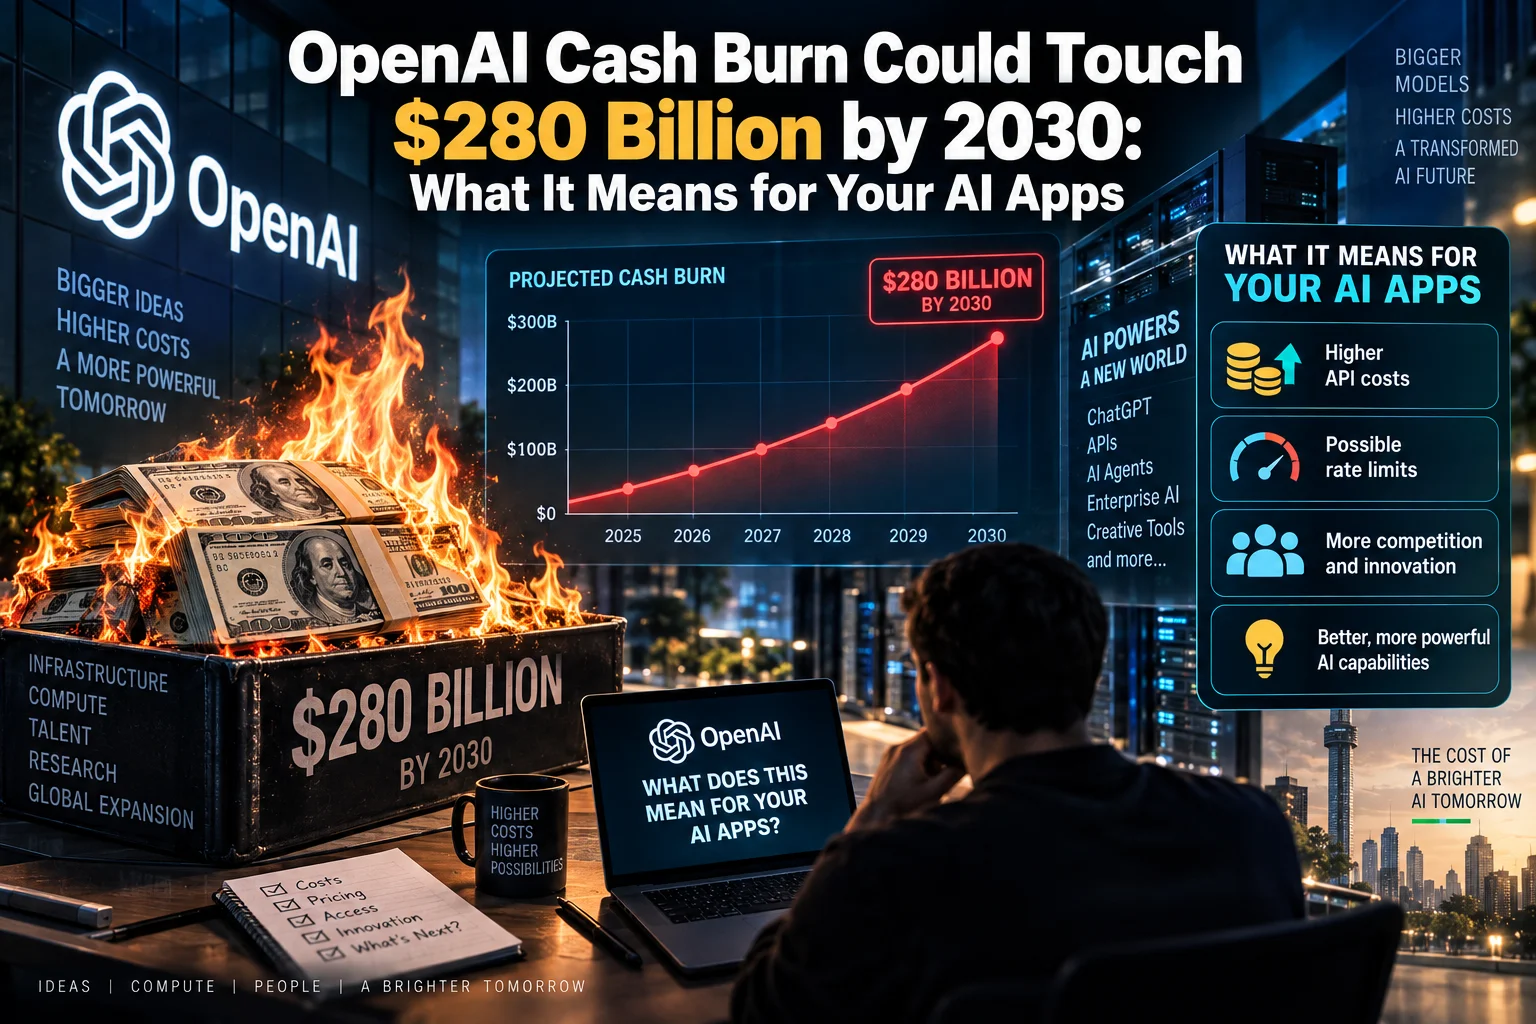
- OpenAI internally projects cumulative cash burn nearing $280 billion (roughly ₹23-24 lakh crore) through 2030 to build and run next-gen AI models.
- The company is exploring funding rounds that could value the ChatGPT maker at nearly $1.2 trillion ahead of a potential public listing.
- Massive computing costs for GPU clusters, custom silicon, data center power contracts, and electricity drive this unprecedented burn rate.
- Indian tech founders and everyday users should prepare for tighter free limits, tiered subscriptions, and aggressive enterprise monetization.
- Indian development teams are already hedging risks by combining frontier APIs with self-hosted open-weight models to keep token bills under control.
What just happened?
Imagine burning ₹24 lakh crore in just a few short years simply to keep server fans spinning and AI models thinking. That is roughly the sheer scale OpenAI is staring at right now.
Reports indicate that OpenAI expects its cumulative cash burn to hover near $280 billion by 2030. To put that figure in perspective for anyone tracking Indian public spending, that is larger than the entire annual budget allocations for several major Indian infrastructure ministries combined, poured straight into data centers, specialized chips, electricity grids, and top-tier AI researchers.
At the same time, the company behind ChatGPT is in discussions with global investors for fresh capital rounds. Those high-stakes talks could push OpenAI's private valuation toward an eye-watering $1.2 trillion as it prepares the ground for an eventual stock market listing.
For decades, software was famous for being a high-margin, asset-light business. You wrote the code once, uploaded it to a server, and millions of users downloaded it without costing you much extra money. Frontier AI completely shattered that old rulebook. Building and running modern reasoning engines feels far closer to running a nationwide telecom network or building commercial nuclear power plants.
Why is the compute bill so ridiculously high?
You might wonder why a company that already collects $20 a month from millions of subscribers needs to burn hundreds of billions of dollars. The simple answer comes down to two heavy operational realities: training costs and inference scale.
Think of training an AI model like teaching a student every book ever written. To train next-generation models, thousands of top-end Nvidia chips and custom accelerators must run uninterrupted for months inside specialized data centers. These server farms consume gigawatts of power, require complex liquid-cooling systems, and demand multi-billion-dollar network fabrics just to exchange data without lag.
Then comes inference, which is what happens every time you ask ChatGPT to debug your code, summarize a PDF, or write a business email. Inference is not free. Every single response requires high-end chips to crunch billions of mathematical calculations in real time.
When hundreds of millions of people use the tool every day, the daily electricity and server wear-and-tear bills pile up at lightning speed. On top of that, OpenAI has to lock in data center capacity years in advance with cloud partners. That means committing tens of billions of dollars to future infrastructure before anyone even knows what consumer software revenues will look like down the road.
How does this hit your wallet and daily apps in India?
A $280 billion spending forecast in Silicon Valley is not just an abstract financial number. It ripples straight into the tools you use on your phone and laptop every single day in India.
First, the era of completely unrestricted free tiers is quietly ending. If every prompt costs real money in server electricity, no company can offer infinite free compute without caps. You will notice stricter daily message limits, slightly slower response times during peak hours for free users, and constant nudges encouraging you to pick up paid plans.
Second, subscription pricing is heading toward split tiers. Right now, a standard ChatGPT Plus plan costs roughly ₹1,999 per month with GST in India. As advanced reasoning engines demand heavier compute cycles, AI providers are already rolling out higher-priced tiers for researchers, power users, and enterprise teams who need continuous access to complex problem-solving tools.
Third, everyday consumer apps are going to pass these costs along. When your favorite shopping app, customer support bot, or food delivery service adds intelligent conversational assistants, someone has to pay the underlying API bill. Over time, those compute costs get bundled into convenience fees, platform surcharges, or paid premium memberships.
What does this mean for Indian startups and tech workers?
If you run an engineering team in Bengaluru, Chennai, or Hyderabad, this cash burn reality is a loud wake-up call for your balance sheet.
Many Indian startups built their initial products entirely on top of OpenAI APIs. While that worked great for fast prototypes, relying exclusively on expensive proprietary endpoints can drain your seed capital fast as your active user count scales up.
Smart engineering teams across India are already adjusting their architecture. Instead of routing every basic query through a heavy frontier model, developers are adopting a hybrid model. Routine tasks like text classification, language translation, or quick search summaries get routed to lightweight, open-weight models running on cost-effective local cloud servers.
High-end proprietary models are then reserved strictly for difficult logic, edge cases, and deep multi-step reasoning. This hybrid approach helps Indian founders keep their margins healthy without sacrificing software quality.
So what should you actually do right now?
If you use AI tools for your daily job or manage software projects, you do not need to hit the panic button, but you do need to be intentional about your spend.
For everyday users and college students, audit your recurring subscriptions. If you are paying ₹2,000 every month just to summarize basic articles or draft casual messages, the standard free models or built-in browser assistants might already be more than enough for your routine tasks.
For developers and product managers, avoid single-vendor lock-in at all costs. Design your backend code so you can switch model providers with minimal friction whenever pricing or latency changes. Learning token optimization, prompt caching, and model distillation will be essential skills for every software engineer in the coming years.
The race to build super-intelligent software is no longer just about who has the cleverest algorithm. It has turned into a brutal battle of financial endurance, where every prompt must eventually pay its own way.




Comments (0)
Be the first to comment!