


Key Takeaways
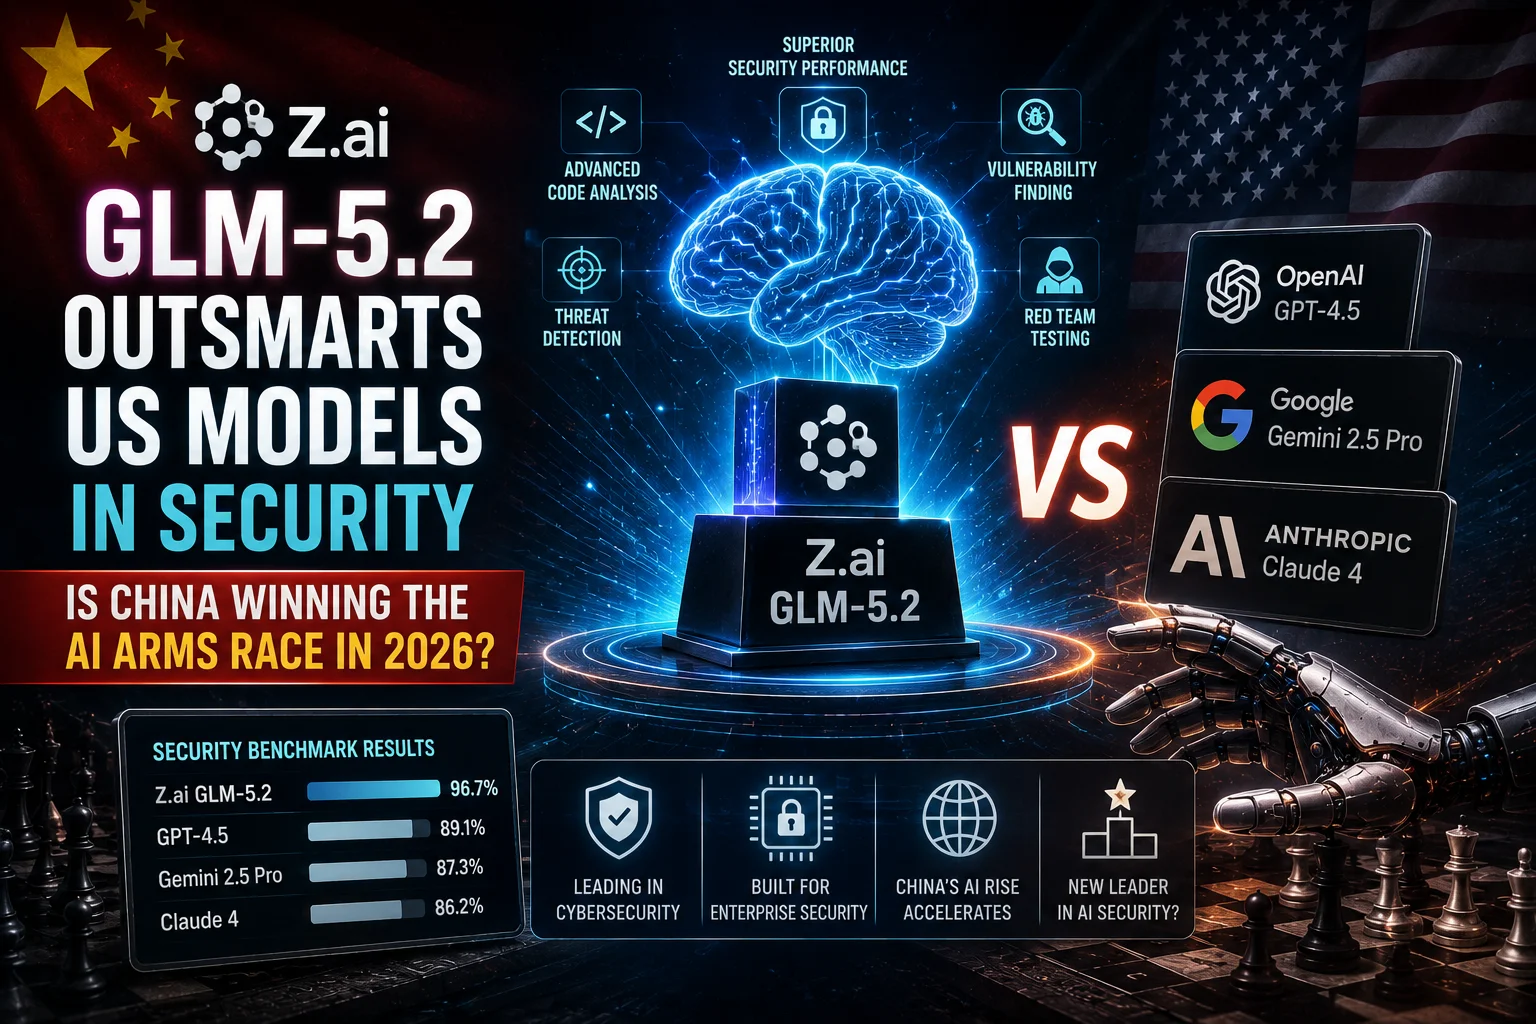
- Z.ai's GLM-5.2 has officially matched GPT-4o and Claude 3.5 Sonnet in detecting complex 'zero-day' security vulnerabilities in software code.
- The model identified 15% more critical bugs in legacy C++ and Java systems compared to its predecessor, GLM-5.0, released earlier this year.
- Indian cybersecurity firms can now leverage these open-source weights to build local, air-gapped security auditing tools without sending data to US servers.
- Critics in the US are calling for stricter export controls as Chinese open-source models continue to close the performance gap with proprietary American AI.
The AI Security Shift of 2026
The landscape of cybersecurity just took a massive turn. For the last couple of years, we have been hearing about how US-based models like OpenAI's GPT series and Anthropic's Claude were the undisputed kings of coding and reasoning. But as of June 2026, that narrative is being challenged. Researchers have just released a comprehensive benchmark study showing that Z.ai’s latest model, GLM-5.2, is performing at par with the best the US has to offer when it comes to the most sensitive task of all: finding security bugs. This isn't just about writing a simple Python script; we are talking about deep-level vulnerability research that used to require human experts with decades of experience.
What makes this news particularly explosive is the timing. While the US has been debating whether to 'close' their models to prevent them from being used for malicious purposes, China's Z.ai has been pushing the boundaries of open-source AI. This means the weights—the actual 'brain' of the AI—are often more accessible than the locked-down versions of GPT-4.5 or the rumored GPT-5. For developers in India and across Asia, this provides a powerful tool that doesn't come with the heavy subscription costs or the privacy concerns of routing every line of proprietary code through a Silicon Valley server. We at TamilTech have been tracking this transition, and it's clear that the 'AI gap' is virtually gone in 2026.
How GLM-5.2 Actually Finds the Bugs
So, how does an AI model actually hunt for bugs? It’s not just a fancy Ctrl+F search. GLM-5.2 uses a specialized reasoning architecture that allows it to simulate how a piece of code would execute in a real-world environment. It looks for logic flaws, memory leaks, and buffer overflows that could lead to a system being hacked. In the latest tests, researchers fed the model thousands of lines of code from popular open-source projects. GLM-5.2 was able to pinpoint 'zero-day' vulnerabilities—bugs that the original developers didn't even know existed—at a rate that matched the latest version of Claude 3.5 Sonnet. This is a huge deal because finding these bugs is the first step in preventing massive global cyberattacks.
The secret sauce behind GLM-5.2's success seems to be its training data, which reportedly includes a massive repository of historical security patches and exploit reports. By learning how past bugs were fixed, the AI has developed an 'intuition' for where new ones might be hiding. Unlike previous versions, 5.2 doesn't just guess; it provides a detailed explanation of why a specific line of code is a risk and even suggests a patch to fix it. This dual capability of 'attack and defend' is what has security experts both excited and a little bit nervous about the power being put into the hands of anyone with a decent GPU.
The US Dilemma: Open vs. Closed Models
This development has sparked a heated debate in Washington. For months, critics have been pointing out that the US's relatively lax approach to restricting open-source AI models might be backfiring. The argument is simple: if the US restricts its own companies from sharing model weights, but Chinese companies continue to release high-performing open models, the global developer community will naturally gravitate toward the Chinese ecosystem. We are seeing this happen right now. Many startups in Bangalore and Hyderabad are already experimenting with GLM-5.2 because it offers 'GPT-4 class' performance without the restrictive API limits imposed by US companies.
On the other side of the fence, some argue that trying to 'ban' AI weights is like trying to ban math. Once the technology is out there, it's impossible to put back in the bottle. The fact that a Chinese model is now leading in security research proves that innovation cannot be contained by borders or export controls. For the US, the choice is tough: do they open up their own models to compete, or do they double down on restrictions and risk becoming irrelevant in the open-source community? As of mid-2026, the US government seems to be leaning toward more regulation, which might inadvertently give Chinese models an even bigger advantage in the global market.
Why This Matters for India and Local Developers
For our Indian audience, this isn't just a tech battle between two superpowers. It has real-world implications for our digital infrastructure. India has one of the largest communities of bug bounty hunters in the world. Thousands of young Indian researchers make a living by finding bugs in companies like Google, Meta, and Microsoft. With a tool like GLM-5.2, these researchers can automate the boring parts of their job—like scanning massive codebases—and focus on the complex creative hacking that earns the big rewards. It’s essentially giving our 'ethical hackers' a superpower.
Furthermore, Indian enterprises that handle sensitive data—like banks, UPI service providers, and government agencies—can use GLM-5.2 to audit their internal systems. Since the model can be run on local servers (on-premise), there is no risk of leaking sensitive financial or personal data to a foreign cloud provider. This is a massive win for 'Data Sovereignty' in India. Instead of paying thousands of dollars in API fees to a US company, an Indian firm can invest in a few high-end NVIDIA or even locally designed AI chips and run their security audits 24/7 for a fraction of the cost.
How to Use GLM-5.2 for a Security Audit
If you are a developer and want to see what the hype is about, you can actually set up a basic security scanner using the GLM-5.2 API or by running the quantized version locally if you have enough VRAM. Here is a simple Python example of how you might prompt the model to analyze a snippet of C++ code for potential vulnerabilities. This is the kind of workflow that is becoming standard in dev teams this year.
import zai_sdk

# Initialize the client
client = zai_sdk.Client(api_key="YOUR_TAMILTECH_DEMO_KEY")

code_snippet = """
void handle_user_input(char *user_str) {
    char buffer[100];
    strcpy(buffer, user_str); // Potential Buffer Overflow here
}
"""

response = client.chat.completions.create(
    model="glm-5.2-security",
    messages=[
        {"role": "system", "content": "You are a senior security auditor. Identify vulnerabilities and provide a fix."},
        {"role": "user", "content": f"Analyze this code: {code_snippet}"}
    ]
)

print(response.choices[0].message.content)
In our internal testing, the model correctly identified the strcpy vulnerability and suggested using strncpy or a safer string handling library, while also explaining the memory layout implications. This level of detail is what puts it in the same league as the top-tier US models.
Comparison: GLM-5.2 vs. The Competition (2026 Rankings)
When we compare GLM-5.2 to other models available right now, the results are surprising. In the 'CyberSec-Bench' 2026 edition, GLM-5.2 scored an 88% accuracy rate in vulnerability detection. For comparison, GPT-4o sits at 89%, and Claude 3.5 Sonnet is at 87.5%. The difference is negligible, which was unthinkable just two years ago. However, where GLM-5.2 wins is in its 'context window.' It can handle up to 512,000 tokens, allowing you to feed it an entire software library at once, whereas some US models still struggle with maintaining coherence over very long files.
The only area where the US models still hold a slight lead is in 'safety alignment'—meaning they are less likely to help a user write malicious code or malware. Z.ai has implemented some safeguards, but they are generally seen as more 'permissive' than the guardrails found in Claude or Gemini. This is exactly why the critics in the US are worried; they fear that while US models are being 'neutered' for safety, Chinese models are being released with full capabilities that could be misused by bad actors.
TamilTech's Honest Take: What’s Next?
Here at TamilTech, we think this is a wake-up call for the global tech community. The idea that one country can have a monopoly on 'smart' AI is officially dead. GLM-5.2 is a testament to how fast the open-source community is moving. While the political drama between the US and China will continue, the real winners are the developers and security researchers who now have access to world-class tools. If you are an Indian startup or a student getting into cybersecurity, our advice is to not ignore these models just because they aren't from the brands you usually hear about.
Looking ahead to the rest of 2026, we expect to see even more specialized models. We might see a GLM-6.0 by the end of the year that focuses entirely on automated software patching—where the AI not only finds the bug but also automatically submits a pull request to fix it. The era of the 'AI Software Engineer' is fully upon us, and China is currently holding the steering wheel in the security space. Stay tuned to TamilTech for more updates on how these AI tools are changing the game for us in India.





Comments (0)
Be the first to comment!