

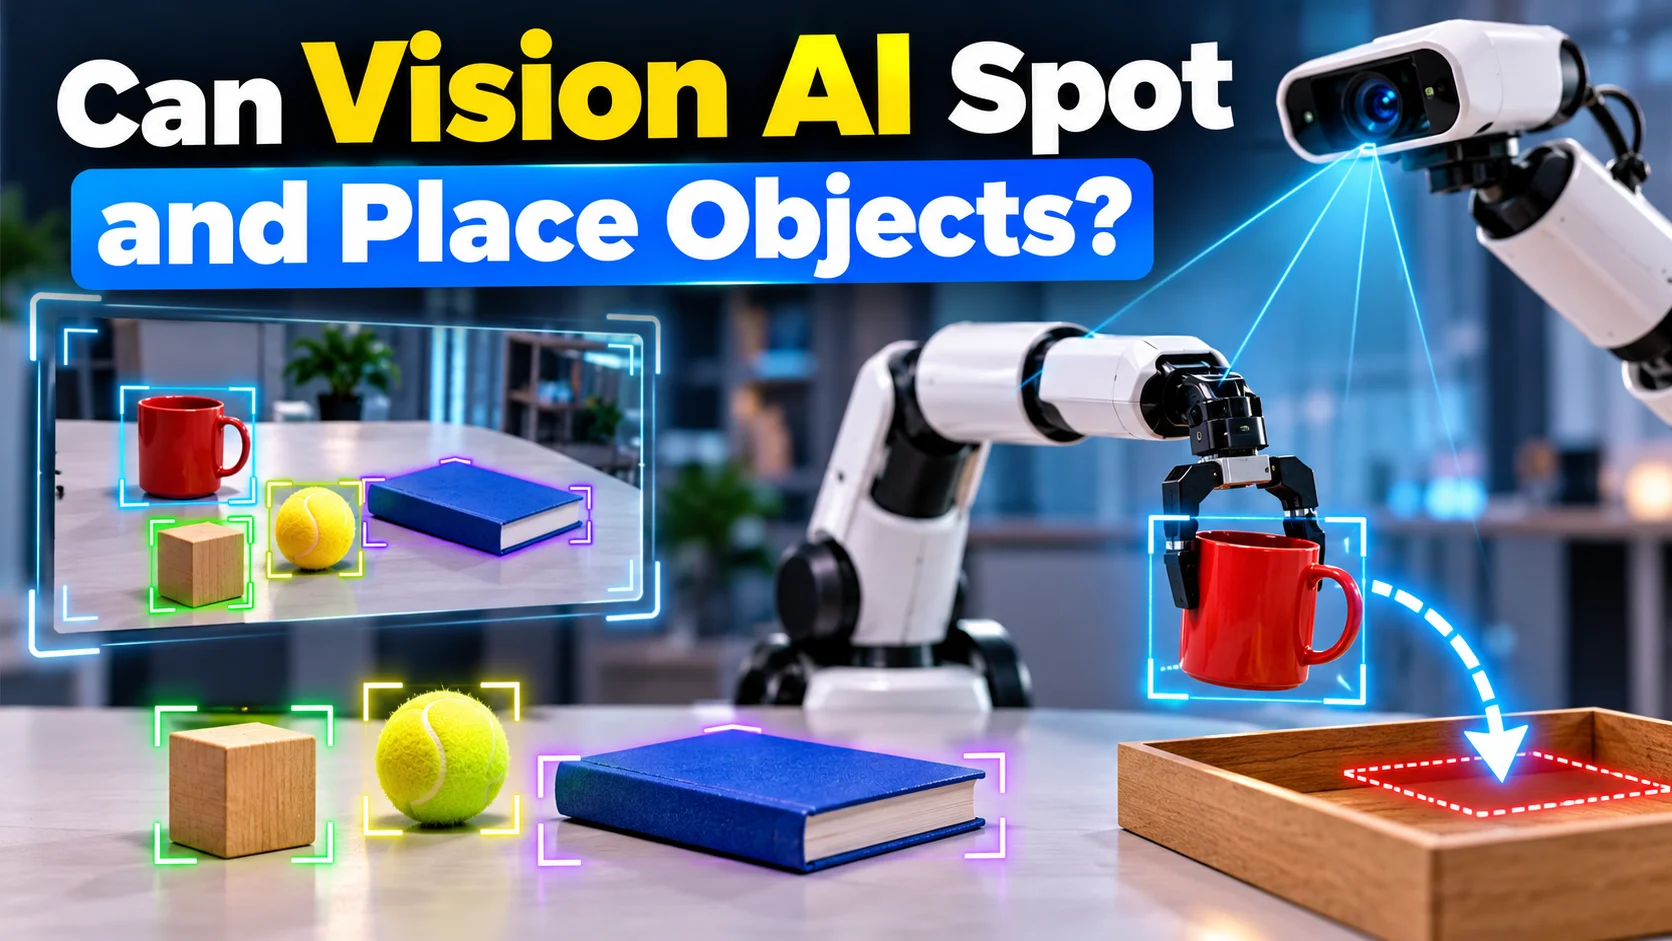
- Current vision-language models waste precious milliseconds typing full sentences just to tell a robot where a box sits.
- Mind Lab introduced MJev-Spatial, a System 1 multimodal architecture that scores spatial options in a single forward pass without generating answer tokens.
- The model uses pretrained query-key (Q-K) projections directly, meaning zero extra parameters added to the backbone network.
- Built on Qwen3.5-4B and trained on 12.3M converted spatial pairs, length-aware batching pushed training throughput up by 30.8%.
- For Indian engineers building quick-response drones, dark-store robotics, or assistive gear, this research offers a practical path away from heavy text decoding.
What is MJev-Spatial in simple terms?
Picture catching a tumbler of hot filter coffee slipping off a tea-stall counter. Your brain does not write a paragraph describing the height of the counter, the angle of descent, and the trajectory of your fingers. You just reach out and grab it. Psychologists call this fast, reactive reflex System 1 thinking.
Today's popular vision-language models do the exact opposite. If you feed an image into a modern vision model and ask where a package sits on a shelf, the model begins autoregressive decoding. It churns out words one by one: "The parcel is located at..." followed by numbers and punctuation. That slow process eats memory, costs GPU cycles, and forces developers to write messy regex scripts just to extract two coordinates.
MJev-Spatial, created by researchers at Mind Lab, flips this setup entirely. Instead of making an AI write text answers to simple visual questions, the architecture frames spatial tasks as a rapid classification decision. It predicts spatial relations, distances, and 2D target points in one forward pass, without spitting out a single generated token.
How does native attention matching actually work?
Think of traditional AI generation like an exam where a student must write a long descriptive answer to get marks. MJev-Spatial turns the exam into a multiple-choice optical mark recognition sheet. The student simply shades circle A, B, or C, and the paper gets graded instantly.
The researchers split spatial intelligence into three everyday challenges: spatial relations (is the phone to the left of the laptop?), numerical distances (how many meters away is the wall?), and coordinate pointing (where should a mechanical gripper touch down?). For choice questions, the candidates are the predefined options. For distances and points, the model uses value bins and image regions that get sharpened through a coarse-to-fine classification pipeline.
Here is the clever engineering trick: MJev-Spatial does not tack on bulky classification heads or add fresh parameters. It takes the pretrained Query (Q) and Key (K) projections already sitting inside the base model and calculates similarity scores directly. Candidate answers act as classes, and the native attention mechanism scores them natively.
Training this setup across 12.3 million question-answer pairs derived from existing spatial datasets required smart data pipelining. The team supervised all coarse-to-fine stages jointly using teacher forcing in a single forward pass. By pairing length-aware global batching with cross-GPU load balancing, they lifted training throughput by 30.8% compared to standard batching strategies. The research details and links are cataloged on Hugging Face at https://huggingface.co/papers/2610.22276.
What makes this different from traditional vision models?
To see why this paper drew over 350 upvotes on Hugging Face, look at what happens behind the scenes when a robot arm runs on a standard multimodal stack versus MJev-Spatial.
With a standard vision-language model, every query launches an autoregressive loop. The system loads context, runs a forward pass for the first word, appends that word to the key-value cache, runs another pass for the second word, and repeats. If the output needs to steer a fast-moving drone or an automated sorting bin in a warehouse, that latency compounds quickly.
MJev-Spatial cuts the entire loop. Because the output space for spatial problems is inherently compact—a discrete choice, a scalar measurement, or a 2D coordinate—generating natural language strings is pure waste. MJev-Spatial evaluates the candidates in one go, outputs the winning score, and stops. No text parsing, no hallucinated syntax, and zero token generation latency.
Which bottlenecks could slow down real-world adoption?
Before rushing to replace your production computer vision pipeline, keep expectations grounded. This is early research code hosted on GitHub with modest initial community stars, not an off-the-shelf SDK ready for enterprise service-level agreements.
First, coarse-to-fine classification works neatly on structured benchmarks, but messy physical environments present real hurdles. Think about a chaotic Indian street scene with tangled overhead cables, moving auto-rickshaws, and uneven footpaths. Discretizing complex 3D environments into neat bins and regions can introduce quantization errors if the fine-grained search grid is too coarse.
Second, the backbone model is Qwen3.5-4B. A 4-billion-parameter foundation is compact by server standards, but running 4B models at 30 frames per second on cheap edge hardware—like an onboard drone controller or a low-cost warehouse scanner—remains tough without aggressive quantization and specialized NPU acceleration.
Finally, the system relies on supervised teacher forcing across converted datasets. If your application involves unique camera distortions, infrared industrial cameras, or unusual fish-eye lenses, you will likely need to re-bin and retrain candidate spaces to fit your hardware.
What should Indian developers build with this next?
For Indian developers, founders, and engineering students, MJev-Spatial points toward practical opportunities where speed matters much more than chatty conversational skills.
Take quick-commerce dark stores run by platforms like Blinkit, Zepto, or Instamart. Automated packing stations and robotic sorters must identify where a pouch of milk or a spice packet sits in a crate within milliseconds. Running giant proprietary vision APIs over cloud connections introduces network lag and runaway API bills. A single-pass 4B model running on local edge compute could classify pick-and-place targets at a fraction of the operating cost.
Another clear avenue is assistive technology. Developing low-cost wearable cameras for visually impaired individuals requires immediate spatial warnings—telling the wearer whether a pothole or step is two feet ahead. Autoregressive models that take a full second to formulate a polite sentence are dangerous in transit. A native attention classifier that triggers audio alerts in real time is far more dependable.
If you want to experiment today, start by reviewing their open-source repository. Pull down the Qwen3.5-4B base, study how the authors implemented coarse-to-fine binning on attention heads, and test whether native Q-K matching can solve your company's coordinate prediction tasks without spinning up heavy autoregressive pipelines.

Comments (0)
Be the first to comment!