

முக்கிய விஷயங்கள்
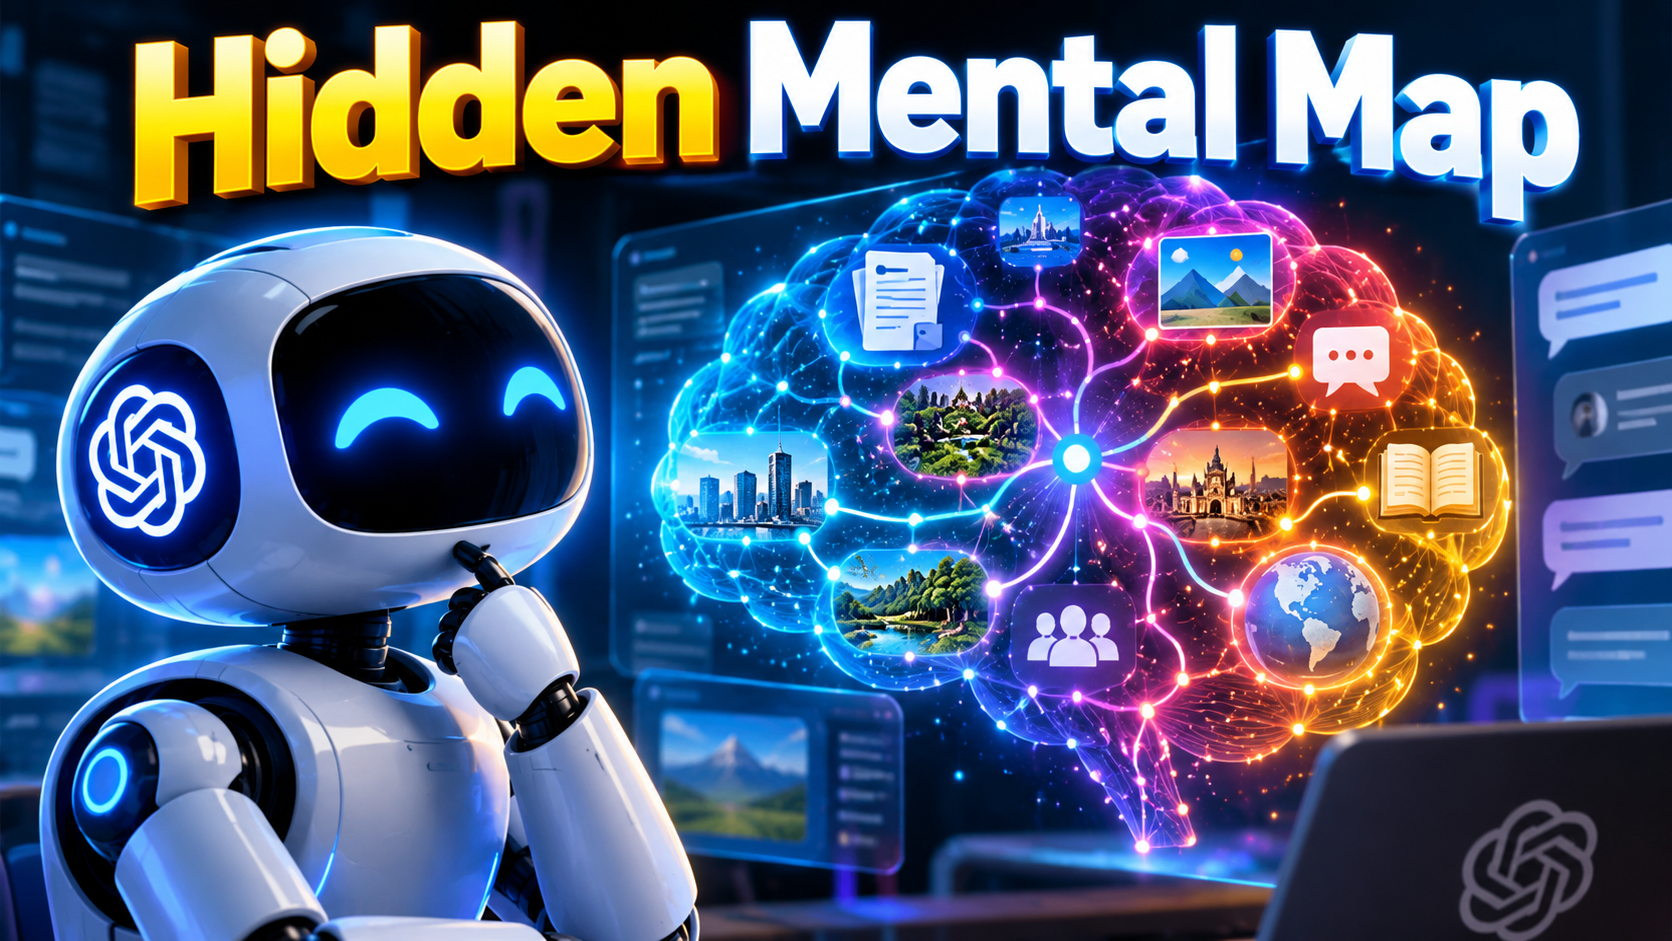
- New research paper 'S-Space' finds that multimodal AI models (ones that read both images and text) have an internal, hidden space that tracks object positions - horizontal, vertical, and distance.
- This isn't something researchers trained into the model on purpose. It showed up naturally, even when you don't ask spatial questions at all.
- The paper got 265 upvotes on Hugging Face and has open code on GitHub (247 stars), which tells you AI researchers worldwide are paying attention.
- It explains why AI vision models sometimes mix up left/right or get confused about 'behind' and 'in front of' - the paper even points to where this breaks down.
- Nothing is shipping in apps yet. This is lab research, not a feature update for your Phone.
What just happened?
Okay picture this. You show ChatGPT or Gemini a photo and ask, "Is the cup to the left of the laptop?" Most of the time, it gets it right. Feels almost normal now, right? But here's the weird part nobody really knew the answer to: how does the model actually know that? Is it genuinely tracking positions inside its brain, or is it just pattern-matching from millions of training images and making a lucky guess?
A research team called MirroS dug into this question properly. Their paper, S-Space: Exploring Spatial Workspace in Multimodal Language Models, says they found something concrete - a specific internal subspace inside these AI models where object positions get stored as actual continuous coordinates. Not words. Not guesses. Coordinates, like a graph.
The paper has quietly become one of the most talked-about AI research drops this month - 265 upvotes on Hugging Face Papers and the code is public on GitHub with 247 stars. For a research paper (not a flashy product launch), that's a big deal in the AI community.
How does this actually work?
Think of it like this. Imagine your brain has a tiny whiteboard that nobody taught you to draw on, but every time you look at a room, you unconsciously sketch where things are - chair here, door there, person standing behind the table. You never "decided" to make that whiteboard. It's just there, running in the background.
That's basically what the researchers call S-Space. It's a layer inside the AI model where, every time it looks at an image, it quietly plots out each object on three invisible axes - left-right (horizontal), up-down (vertical), and near-far (distance).
The researchers found this subspace by checking how the model's internal activations change when it answers spatial questions. But here's the genuinely surprising bit from the abstract: this spatial map stays readable even when you ask the model something totally non-spatial, like "what colour is the cup?" Meaning, the model isn't building this map just to answer your spatial question - it's already there, all the time, as part of how the model "sees".
The paper also claims this workspace does more than just store positions. When the model needs to imagine the scene from a different angle - say, "what would this room look like from the dog's point of view?" - the internal reasoning actually transforms the coordinates in that same workspace. And when the model gives you a verbal answer, it selectively pulls from this space; the researchers tested this with causal interventions (basically poking the internal activations) that changed spatial answers while mostly leaving other answers untouched.
There's a fun bit too - the paper says S-Space even assigns a position to the observer (you, the person asking) and to things not even visible in the photo, and it connects literal directions (like "left") with abstract language meaning. That's the part AI nerds get excited about, because it hints at how far language training alone can take a model toward real spatial understanding - and where it quietly runs out of road.
And that's the most useful part of this paper for anyone who builds with AI: it doesn't just describe the magic, it finds the bug. The researchers used S-Space itself as a diagnostic tool and found that direction words get tangled between two different reference frames - cardinal directions versus image-relative directions. They also found what they call a perception-computation bottleneck, basically a specific point where the model's spatial reasoning breaks down even though it perceived the scene correctly.
What changes for people in India?
Let's be real - most of us aren't training foundation models in a lab. But this research still touches a lot of work happening in Indian tech right now.
If you're a developer building on top of vision-language models for things like warehouse robotics, drone-based agriculture monitoring, or retail shelf-scanning apps for companies like Flipkart sellers or local kirana chains, spatial accuracy is exactly where your app quietly fails in demos. This paper gives the AI community a map (pun intended) of why those failures happen - cardinal vs image-relative direction confusion is a very specific, fixable-sounding bug, not just "AI is dumb sometimes".
For students doing ML research in Indian colleges - IITs, IIITs, and the growing number of AI labs coming up in Bengaluru, Hyderabad, Pune - this is the kind of interpretability paper that's genuinely good to read and even replicate. The code is open on GitHub. If you're doing a final-year project on vision-language models, poking around this repo is a much better use of your time than another "fine-tune a chatbot" project everyone's already done.
For startups building AI products - navigation assistants, AR shopping apps, accessibility tools for visually impaired users that describe surroundings - understanding that models have this internal spatial layer means future tuning and evaluation can target it directly instead of just throwing more training data at the problem and hoping.
None of this means your UPI app or food delivery app is about to get spatial AI superpowers next week. It doesn't work that way.
What should you do now?
Nothing urgent, honestly. This is early-stage interpretability research - the kind of paper that shapes how the next generation of multimodal models get built and tested, not something that lands in a Model update notification on your Phone tomorrow.
If you're building AI products in India right now, the practical takeaway is simpler: when your vision-AI feature struggles with spatial questions - left/right mix-ups, wrong distance estimates, confused "in front of vs behind" answers - know that it's a documented, studied weakness, not just your prompt being bad. That alone should save you a few frustrated debugging nights.
If you're curious to go deeper, the paper page is public at huggingface.co/papers/2610.13527, and the GitHub repo lets you actually run the analysis yourself if you've got the GPU access and patience for it.
Worth keeping an eye on which major AI labs cite or build on this work next - that's usually the real signal for whether a research idea becomes a product feature or stays a fascinating footnote.

Comments (0)
Be the first to comment!